

Most AI pilots in the UAE end the same way. Someone runs a demo, everyone nods, budget for rollout gets discussed vaguely, and six months later nobody can name what the pilot decided. That is what a failed AI pilot project looks like.
The problem is not the technology. The pilot was designed backward.
A pilot is an experiment, not a demo, and an experiment needs its success criteria written down before you touch a single tool. Here are the seven decisions that turn a pilot into an answer.
Key Takeaways
- 95% of AI pilots produce no P&L return — MIT Media Lab's Project NANDA report found enterprise generative AI pilots almost universally fail to move the P&L, because success criteria were never written down before launch.
- Define go/no-go criteria before touching any tool — Fix the metric, the threshold, the timeframe, and the named person with final authority to call it — all before configuration starts.
- Score Arabic and English outputs separately — Averaging the two hides quality drops in the weaker language; run pure Arabic, pure English, and mixed or Arabizi samples and report all three numbers.
- End the pilot with a written decision — "We think it worked" is not a conclusion. The deliverable is a one-page document covering what was tested, the criteria, the data, and the recommendation — what the CFO reads, not a slide deck.
- Stopping a pilot can be the right call — Proceed, re-pilot, and stop are all legitimate outcomes; recommending stop and protecting the budget for a better opportunity counts as pilot success.
Why Most AI Pilots Produce Nothing You Can Act On
According to MIT Media Lab's Project NANDA report The GenAI Divide: State of AI in Business 2025, 95% of enterprise generative AI pilots produce no measurable P&L return. Not "some fail." Almost all of them.
The cause is structural. Pilots get treated as technology demonstrations, with success defined after the results are in.
Someone runs the tool, produces some output, and the room decides collectively whether it "felt like it worked." No metric was set, no threshold agreed, so any result can be argued into a win.
Pressure to launch quickly makes this worse in the UAE than most markets. Microsoft's AI Economy Institute AI Diffusion Report puts UAE working-age AI usage at 70.1% against a global average of 17.8%.
That gap creates board-level urgency, and urgency produces pilots that prove nothing. The alternative is a pilot that closes with a formal go/no-go recommendation, not a vague "it went well."
Stanford's AI Index report tracks adoption, cost and capability trends year on year, and is a useful check against vendor claims.
Decide What Proof Looks Like Before You Switch Anything On
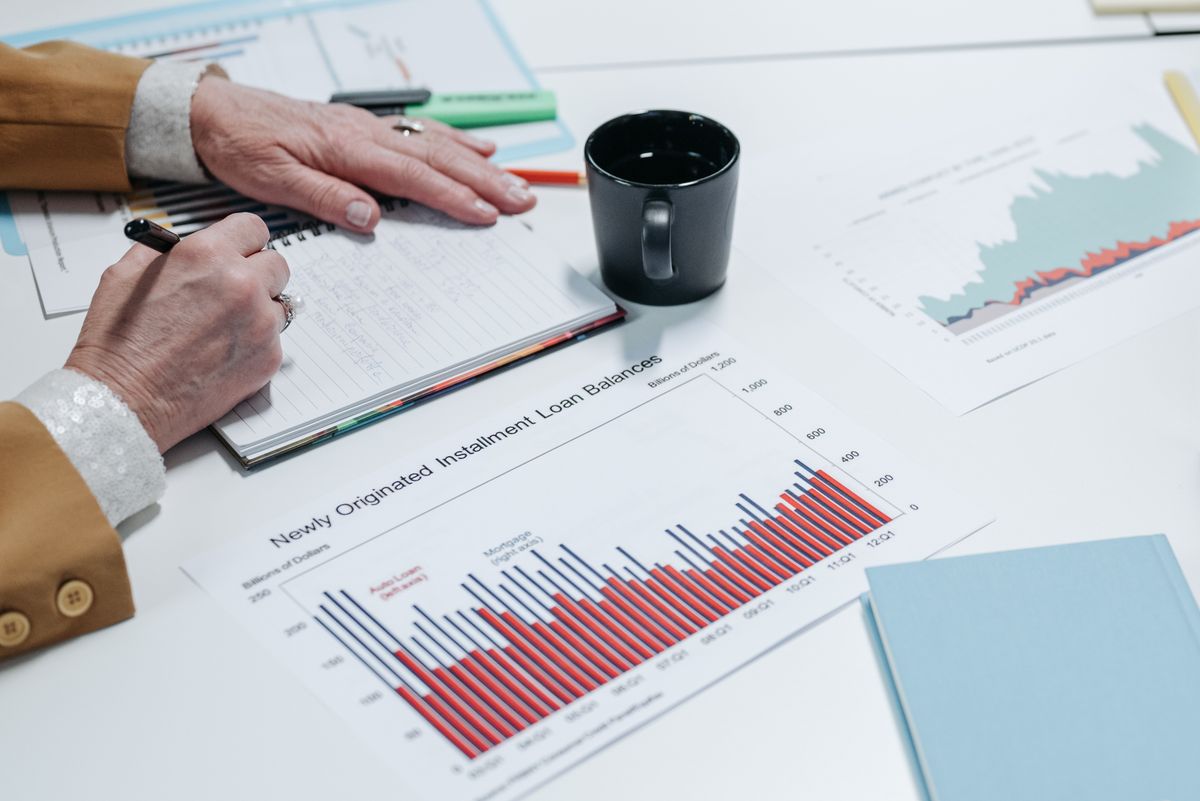
Photo: Pavel Danilyuk on Pexels
Every good AI pilot project answers exactly one decision. Not "let's see what AI can do."
Something like "should we automate first-line WhatsApp triage, and with a rule-based bot or an LLM?" Write it down.
Then write the criteria that will answer it. Concretely: the metric, the threshold, the timeframe, and the person with final authority to call it.
"Reduce median time-to-first-response from 42 minutes to under 10, over four weeks of live traffic, called by the head of customer service." That is a decision metric.
Vanity metrics get you nothing. "The demo ran cleanly" is a vanity metric.
Only decision metrics (time per task, error rate, cost per output, resolution rate) justify a budget request. This step also fixes scope: anything not connected to the decision can wait for the wider 90-day automation plan.
Pick a Process Where Your AI Pilot Can Actually Read the Results
A pilotable process has three properties: enough volume to generate real signal, a current state that can be measured, and outputs someone other than the vendor can objectively assess.
UAE friction rules out some obvious candidates. Customer messages arrive as mixed Arabic-English WhatsApp threads with Arabizi tossed in.
Supporting documents come through as phone photos of trade licences or Emirates IDs. Federal Decree-Law No. 45 of 2021 (PDPL) constrains what personal data can flow through a non-local model.
Strong starting candidates for UAE SMEs share the opposite profile: high volume, measurable current cost, clear standard for a good output. Inbound WhatsApp triage. Quote generation from a standard template.
Invoice and document data extraction. Our sibling piece on five automations that pay back in under 60 days covers which processes hit that sweet spot.
Measure the Baseline Before Your AI Pilot Begins
You cannot prove improvement against a baseline you never captured. Log the current process in real time for a week or two before the pilot starts. Time per task, error rate, cost, volume, measured with the metrics from your go/no-go criteria.
The common mistake: measuring how the process should work per the procedure document, not how it actually works today. Baselines have to be observed, not assumed.
Ask the person who does the job to keep a simple log for a fortnight. The gap between written procedure and observed reality is often the pilot's most useful finding.
Document who does the task, in which language, and on which tools. Any of those variables can shift during the pilot and confound the results.
For businesses in the AED 10,000 to 50,000 band, a clean baseline often shows the process can be fixed with a rule-based workflow rather than an AI model. Catching that early saves the pilot budget.
Chain-of-thought prompting comes from a 2022 paper by Wei and colleagues, which showed that asking a model to work through intermediate steps improves multi-step reasoning.
Run the AI Pilot With a Scope That Fits on One Page
Photo: DS stories on Pexels
One process. One team. One decision question.
Resist scope expansion mid-pilot. Adding a second use case makes results unreadable and budgets unjustifiable. When someone says "while we're at it, could we also...", the answer is no.
Fix the timeline before day one. Long enough to gather signal on real transaction volume, short enough that the team stays engaged.
Four to eight weeks covers most SME cases. Agree the end date in writing before anything switches on.
Assign a single internal owner. Not the vendor, not IT, not "the AI committee." One named person accountable for data quality and daily operation, ideally whoever currently does the job.
Team adoption is a pilot variable, not an afterthought. Our piece on what a team of five can realistically run on a small budget covers the practical side.
Read Your Pilot Results Without Moving the Goalposts
Compare post-pilot data to your observed baseline, not the vendor demo. The demo ran on curated inputs.
Your pilot ran on real messages, real documents, real edge cases. Those are different worlds, and the comparison has to be honest about which one you are in.
Watch for the novelty effect. Team output usually improves in the first week or two of any change, then regresses toward the old mean.
Early pilot data may not represent steady-state performance. Evaluate the last two weeks separately from the first.
Bilingual quality has to be assessed on separate streams, never averaged. An AI that handles English well can quietly drop in quality on Arabic or mixed inputs; the blended average looks acceptable while your Arabic-speaking customers get bad answers.
Report both numbers. IBM's Institute for Business Value found that 84% of AI-adopting businesses met or exceeded their ROI, but only after rigorous evaluation, not selective readings.
Turn the Pilot Evidence Into a Go/No-Go Decision
A pilot that ends with "we think it worked" has not ended. The deliverable is a one-page decision document: what was tested, what the criteria were, what the data showed, and the recommendation. That is what the CFO reads, not a slide deck.
Three outcomes are valid. Proceed to production. Re-pilot with modified scope when the concept is sound but one variable (data quality, integration, language coverage) needs another cycle.
Stop, when evidence says the juice is not worth the squeeze. All three are legitimate; stopping and protecting budget for a better opportunity is a success.
Proceed only when you can answer three questions in writing: who maintains the system, what is the response plan when it breaks, and how has the team been trained. Those are the questions that kill AI projects in handover, and the pilot-to-production handover is where most quietly die.
McKinsey's State of AI: Global Survey 2025 reports only 11% of companies have scaled generative AI. The decision document bridges the gap.
If you are staring at a pilot proposal right now and cannot tell whether the criteria will hold, book a free 30-minute consultation. We will tell you honestly, and if a pilot does not make sense, we will say so.
Not every pilot ends the same way, and the right response depends on what the evidence actually shows.
| Outcome | When to choose it | What happens next |
|---|---|---|
| Proceed | Criteria met; you can answer who maintains it, the response plan, and training | Move to production handover |
| Re-pilot | Concept sound but one variable (data quality, integration, language coverage) needs another cycle | Adjust that variable and rerun |
| Stop | Evidence shows the juice is not worth the squeeze | Protect the budget and end the pilot |
Related reading
FAQ
How long should an AI pilot project run?
Long enough to observe real transaction volume, short enough to keep the team engaged. For most UAE SMEs that means four to eight weeks. Set the end date before you start; open-ended pilots drift and never produce a decision.
How do I write go/no-go criteria before an AI pilot starts?
Write one sentence with four parts: the metric, the threshold that counts as success, the timeframe over which you will measure it, and the named person with authority to call the decision. If you cannot fill in all four, you are not ready to launch.
What is the difference between an AI pilot and a proof of concept?
A proof of concept answers "can the technology do this at all," usually on sample data. A pilot answers "does it work on our real data, well enough to justify rolling it out." The pilot answers the P&L question; the PoC answers the feasibility question.
How much does running an AI pilot project cost for a UAE SME?
For a single-process pilot in the AED 10,000 to 50,000 range, most SMEs can cover configuration, integration, baseline, and post-pilot evaluation. Costs climb sharply when scope expands or custom model work is added. A tight pilot with one owner keeps the number in that band.
What data do I need to collect before starting an AI pilot?
Two weeks of observed baseline data on whatever the go/no-go criteria will measure: time per task, error rate, volume, cost. Plus context: who performs the task, in which language, on which tools. Skip this step and the post-pilot comparison collapses.
When is the right time to stop an AI pilot that is not delivering results?
When the pre-agreed end date arrives and the criteria have not been met, or earlier if a fundamental blocker (data access, PDPL, integration reality) surfaces that the pilot cannot resolve. Stopping is a legitimate outcome. Extending an unclear pilot indefinitely is the wrong move.
How do I handle Arabic and English mixed data in an AI pilot?
Evaluate the two language streams separately, never averaged. Run pure Arabic, pure English, and mixed or Arabizi samples through the system and score each independently.
Report all three numbers in the decision document. If Arabic performance is materially worse, that is a re-pilot signal.


